Note: This environment variable is required for fully deterministic CuBLAS ops on CUDA >= 10.2 when
reproducible=Trueis set below. Without it, PyTorch raises aRuntimeErrorinstead of training deterministically. It must be set beforetorchis imported. See the README FAQ for details.
%env CUBLAS_WORKSPACE_CONFIG=:16:8
How To Use XModalix
X-Modalix is our implementation of a cross-modal autoencoder.
This tutorial follows the structure of Getting Started - Vanillix, but is less extensive because our pipeline works similarly across different architectures. Here, we focus only on X-Modalix specifics.
AUTOENCODIX supports far more functionality than shown here, so we’ll also point to advanced tutorials where relevant.
IMPORTANT
This tutorial only shows the specifics of the XModalix pipeline. If you're unfamiliar with general concepts,
we recommend following theGetting Started - Vanillixtutorial first.
XModalix Theory
Before we show data preparation and X-Modalix training, we provide background on cross-modal VAEs as proposed by Yang & Uhler.
The core idea of a cross-modal autoencoder is to align the latent spaces of different data modalities.
Once the latent distributions are aligned, we can translate between modalities by feeding data from one modality into its encoder and then passing the latent space to the decoder of the target modality.
The underlying models are separate VAEs—one for each data modality—which are trained in parallel. Their latent spaces are closely aligned so that modalities are hard to discriminate, but sample variation is preserved.
To achieve this alignment, the VAE loss function is extended with the following terms:
Adversarial loss term: In parallel with the VAEs, a third neural network (latent space classifier) is trained to discriminate the embeddings of different modalities. Analogous to a GAN, the inverse of this classifier loss is added to the VAE loss to enforce latent space alignment.
Paired loss term: Alignment is further enforced by minimizing the distance between samples with paired measurements across modalities. While unpaired samples are allowed, we recommend that most samples are paired (present in all modalities).
Class-based loss term: This semi-supervised term minimizes distances among samples of the same class. Class membership is defined in the annotation data (e.g., cancer type, cell type). In each iteration, the class mean in the latent space is computed, and distances from individual samples to the class mean are minimized. See our
Preprint [TODO]for more details.
What You'll Learn
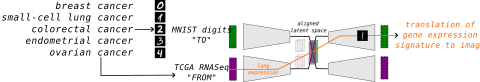
As a showcase for data modality translation with X-Modalix, we will use cancer gene expression from TCGA in combination with handwritten digits from the MNIST dataset.
Our goal is to translate gene expression signatures of five selected cancer subtypes into images of digits, with each cancer subtype class mapped to a digit between 0–4.
In practice, these images could be histopathological images or any other data modality.
While following this showcase, you will learn how to:
- Initialize the pipeline and run it.
- Understand the X-Modalix-specific pipeline steps (paired vs. unpaired data).
- Access X-Modalix-specific results (sub-results for modality autoencoders).
- Visualize and evaluate the outputs.
- Apply custom parameters or architecture
- Save, load, and reuse a trained pipeline.
Let’s get started! 🚀
1) Initialize and Run XModalix
In this example, we read our input data from files.
The file locations are defined in the config via a section called DataConfig (see details in the Python code below).
We highlight a few custom config parameters for XModalix. For a deeper dive into the config object, see [1]:
pretrain_epochs: Before training the full X-Modalix, the sub-VAEs of each modality can be pretrained. This parameter can be set globally for all modalities or individually per modality and specifies the number of pretraining epochs.gamma: Hyperparameter to weight the adversarial loss term.delta_pair: Hyperparameter to weight the paired loss term.delta_class: Hyperparameter to weight the class-based loss term.
❗❗ Requirements: Getting Tutorial Data ❗❗
The data for this tutorial is hosted on Hugging Face Hub (autoencodix/tcga).
Extra 2: Get correct path
We assume you are in the root of the package. The following code ensures that the correct paths are used. [1] Tutorials/DeepDives/ConfigTutorial.ipynb
import os

p = os.getcwd()
d = "autoencodix_package"
if d not in p:
    raise FileNotFoundError(f"'{d}' not found in path: {p}")
os.chdir(os.sep.join(p.split(os.sep)[: p.split(os.sep).index(d) + 1]))
print(f"Changed to: {os.getcwd()}")
Extra 3: Data Assumptions
X-Modalix supports two special cases:
(a) image data, and
(b) unpaired data.
This introduces specific requirements for the input data. In the config object, the DataConfig must be populated with the relevant information. Example code:
imganno_file = os.path.join("data/XModalix-Tut-data/tcga_mappings.txt")
rna_file = os.path.join("data/XModalix-Tut-data/combined_rnaseq_formatted.parquet")
img_root = os.path.join("data/XModalix-Tut-data/images/tcga_fake")
clin_file = os.path.join("data/XModalix-Tut-data/combined_clin_formatted.parquet")

dc = DataConfig(
    data_info={
        "img": DataInfo(
            file_path=img_root,
            data_type="IMG",
            scaling="MINMAX",
            translate_direction="to",
            pretrain_epochs=3,
            # extra_anno_file=imganno_file,
        ),
        "rna": DataInfo(
            file_path=rna_file,
            data_type="NUMERIC",
            scaling="MINMAX",
            translate_direction="from",
        ),
        "anno": DataInfo(
            file_path=clin_file,
            data_type="ANNOTATION",
            sep="\t"
        ),
    }
)
Image Data Requirements
- Specify the root folder where the images are located. The preprocessor will automatically read all images and convert them into tensors.
- Supported image extensions (case-insensitive):
".jpg",".jpeg",".png",".tif",".tiff". - A mapping between each image filename (without directories) and a
sample_idis required, along with any additional metadata.
To provide this mapping, you must supply a global annotation file that contains all sample_ids and metadata columns, including one column with the image paths.
- Use the config parameter
img_path_colto define the name of the column containing image paths (default:"img_paths"). - See your
clin_filefor an example.
Translation Direction
- X-Modalix trains a shared latent alignment, enabling translation between all modalities.
- To keep results consistent, users should define a
translate_directionin the config. - If you want to change the direction or translate a different pair, you can specify this in the
predictstep (see Section 3).
import os
import pandas as pd
import autoencodix as acx

from autoencodix.configs.xmodalix_config import XModalixConfig
from autoencodix.configs.default_config import DataConfig, DataInfo, DataCase
from huggingface_hub import hf_hub_download
print(f"Current directory: {os.getcwd()}")

HF_REPO_ID = "autoencodix/tcga"
clin_path = hf_hub_download(repo_id=HF_REPO_ID, repo_type="dataset", filename="clinical.parquet")
mapping_path = hf_hub_download(
    repo_id=HF_REPO_ID, repo_type="dataset", filename="xmodalix/tcga_image_mappings.txt"
)

# The base clinical file has no image column; the XModalix image mapping is a separate,
# per-architecture extension that we join in here (left join: not every sample has an image).
clin_df = pd.read_parquet(clin_path)
mapping_df = pd.read_csv(mapping_path, sep="\t", index_col="sample_ids")
clin_df["img_paths"] = mapping_df["img_paths"]

os.makedirs("data/raw", exist_ok=True)
clin_file = os.path.join("data/raw", "xmodalix_clinical.parquet")
clin_df.to_parquet(clin_file)

print("First five image paths:")
print(clin_df["img_paths"].to_list()[0:5])
print("\n")
clin_df.head()
Another way is to provide a image-specific annotation file in with the extra_anno_file parameter of the DataInfo object in the DataConfig.
Here you need to map the sample_id (index) to the image path and can add addtional metadata columns like we did in our imganno_file.
We recommend the first option of a global annotation file.
imganno_file = hf_hub_download(
    repo_id="autoencodix/tcga", repo_type="dataset", filename="xmodalix/tcga_image_mappings.txt"
)
img_anno_df = pd.read_csv(imganno_file, sep="\t", index_col=0)
img_anno_df.head()
1) Initialize and Run XModalix
In this section, we demonstrate how to set up the configuration to account for the data requirements and highlight the custom XModalix parameters.
For a more in-depth guide on the configuration parameters and input data, see:
[1] Tutorials/DeepDives/ConfigTutorial.ipynb
[2] Tutorials/DeepDives/InputDataTutorials.ipynb
import zipfile

rna_file = hf_hub_download(repo_id="autoencodix/tcga", repo_type="dataset", filename="rna.parquet")

images_zip = hf_hub_download(
    repo_id="autoencodix/tcga", repo_type="dataset", filename="xmodalix/tcga_fake_images.zip"
)
images_extract_dir = os.path.join("data/raw", "xmodalix_images")
if not os.path.isdir(os.path.join(images_extract_dir, "tcga_fake")):
    with zipfile.ZipFile(images_zip) as zf:
        zf.extractall(images_extract_dir)
img_root = os.path.join(images_extract_dir, "tcga_fake")

xmodalix_config = XModalixConfig(
    checkpoint_interval=100,
    class_param="CANCER_TYPE",
    epochs=100,
    beta=0.1,
    gamma=10,
    delta_class=100,
    delta_pair=300,
    latent_dim=6,
    k_filter=1000,
    batch_size=1014,
    learning_rate=0.0005,
    requires_paired=False,
    loss_reduction="sum",
    pin_memory=False,
    data_case=DataCase.IMG_TO_BULK,
    data_config=DataConfig(
        data_info={
            "img": DataInfo(
                file_path=img_root,
                img_height_resize=32,
                img_width_resize=32,
                data_type="IMG",
                scaling="STANDARD",
                translate_direction="to",
                pretrain_epochs=50,
            ),

            "rna": DataInfo(
                file_path=rna_file,
                data_type="NUMERIC",
                scaling="STANDARD",
                pretrain_epochs=0,
                translate_direction="from",
            ),

            "anno": DataInfo(file_path=clin_file, data_type="ANNOTATION", sep="\t"),
        },
        annotation_columns=["CANCER_TYPE_ACRONYM"],
    ),
)

xmodalix = acx.XModalix(config=xmodalix_config)
result = xmodalix.run()
xmodalix.predict()
2) XModalix Specific Steps
XModalix does not introduce additional pipeline steps. However, its preprocessing and training differ slightly from Varix and Vanillix. XModalix processes each data modality individually and therefore supports unpaired data input.
It is also possible to re-run the predict step and change the translation pairs or direction by providing the from_key and to_key arguments with the string keys that define your data modalities (e.g., "rna" and "img" in our case). See the code below for details.
Furthermore, the visualization and evaluation steps produce outputs that differ somewhat from the other pipelines, which we will focus on in Section 4.
# Initially, we translated from RNA to image. Now we can use the trained model
# to re-run the translation with switched pairs.
# ATTENTION: This will overwrite the existing result object, so we create a backup first.
from copy import deepcopy

backup_result = deepcopy(result)
result_flipped = xmodalix.predict(from_key="img", to_key="rna")
3) Access XModalix Results
Accessing the results works slightly differently for XModalix because we have:
Multiple latent spaces (one for each data modality).
Not just reconstructions, but also
translationsandreference translations.
Reference translations are reconstructions within the same data modality as the translation split.
For example, if we translate fromrnatoimg, the reference translation is the reconstruction fromimgtoimg.
These translations can be accessed via thereconstructionsattribute of theresultobject.
First, use the usualTrainingDynamicsAPI via.get(), which returns a dict containing each data modality’s translation and reference translation.Multiple losses.
These are accessed via thesub_lossesattribute of theresultobject. This is aDictofTrainingDynamics.
First, select the loss type you’re interested in, then work with the standardTrainingDynamicsAPI.
See the code below for examples and [3] for more details:
print("Find available loss types")
print(backup_result.sub_losses.keys())
print("Get adver_loss for training")
backup_result.sub_losses.get("adver_loss").get(split="train")
print("Get reconstruction keys")
# Frist define split and epoch you're interested in
# usually test split (there are no epochs, so by default this is always epoch=-1)
recons = backup_result.reconstructions.get(split="test", epoch=-1)
print(recons.keys())
print("Getting Translation")
trans = recons.get("translation")
print(f"shape of translation: {trans.shape}")
We can acutally plot a sample image here
import matplotlib.pyplot as plt

sample = trans[0, 0, :, :]
plt.imshow(sample)
plt.show()
Accessing the latent spaces works analogously.
4) Visualize XModalix
XModalix results can be inspected by similar plots as other architectures:
- loss curves via
show_loss(plot_type="absolute|relative") - latent spaces via
show_latent_space(plot_type="Ridgeline|2D-scatter")Latent space plotting will plot for each VAE per modality and can be used to check if latent space alignment across modality was achieved during combined training.
Loss curves
Loss curves can be plotted like for all autoencoders:
xmodalix.visualizer.show_loss(plot_type="absolute")
In aggregated_sub_losses all sub-VAE's are aggregated collecting their reconstruction losses as well as KL-divergence loss term.
All sub-losses are stored in sub_loss attribute of the result where you can access individual VAE's like this:
backup_result.sub_losses.get("multi_bulk.rna.recon_loss").get(split="train")[0:5] ## First five epochs of training reconstruction loss for RNA modality
Due to the complexity of loss terms in XModalix, a relative contribution of loss terms to overall is useful to find best loss term weight combination:
xmodalix.visualizer.show_loss(plot_type="relative")
Latent space alignment
Latent space can be visualized as 2D representation or Ridgeline representation as before. But now for each modality. A good alignment will be visible if they match and show similarity:
xmodalix.visualizer.show_latent_space(
	result=backup_result,
	plot_type="2D-scatter"
	)
Specific XModalix visualizations
To inspect translation quality of XModalix reconstructions we provide two plots:
show_2D_translationshows a 2D representation created by e.g. UMAP of the high-dimensional input data vs. the reconstructed translation using the other modality as inputshow_image_translationif your target modality for translation is an image, this can be used to visually compare original images to translated images (cross-modality) and reference images of the image VAE inside the XModalix. A "good" XModalix can be seen in 1) if 2D representation of input and translation show high structural similarity and in 2) if translated images look similar to original images from the test-set which was not part of the training.
2D translation
fig = xmodalix.visualizer.show_2D_translation(
	result=backup_result,
	translated_modality="img.img",
	param="CANCER_TYPE_ACRONYM",
	reducer="PCA",
)
Image translation
fig = xmodalix.visualizer.show_image_translation(  # ty: ignore
        result=backup_result,
        from_key ="mult_bulk.rna",
        to_key = "img.img",
		n_sample_per_class = 3,
        param = "CANCER_TYPE",
    )
5) Evaluate
5.1 Embedding evaluation
Beyond visual inspection and representation of XModalix results, you can evaluate VAE embeddings as before with the evaluate step.
This will perform embedding evaluatation for downstream tasks similarly as for a normal VAE (varix).
Since XModalix is composed of as many VAE's as modalities, each embedding will be evaluated independently.
from sklearn.svm import SVC

my_classifier = SVC(kernel="rbf", probability=True) # You can provide any sklearn classifier here
my_metric = "roc_auc_ovo" # You can provide any sklearn metric here

params = ["CANCER_TYPE_ACRONYM"]
result = xmodalix.evaluate(
	ml_model_class = my_classifier,
	params=params,
	metric_class = my_metric,
	reference_methods= ["PCA"] # We compare XModalix embeddings to PCA embeddings
)
Then we can visualize the evaluation results as bar plots
fig = xmodalix.visualizer.show_evaluation(
	param=params[0], 	# Only one param at a time
	metric = my_metric,		# Needs to be specificied in case multiple metrics were used
	ml_alg=str(my_classifier),	# Needs to be specificied in case multiple classifiers were used
)
We can see that both image VAE (bottom, right) and RNA VAE (top, right) latent space embeddings have similar predictive power for cancer type classification.
5.2 Comparison to a Imagix
Since XModalix VAE's for each modalities are coupled by a joint loss, we offer a function xmodalix.evaluator.pure_vae_comparison() for the image case which will compare translated (from -> to modality) and reference (to -> to) image reconstructions of XModalix with a pure image VAE (Imagix) reconstruction capability.
Prior comparison this pure Imagix needs to be trained on the same data and ideally with a similar config as the XModalix:
from autoencodix.configs.default_config import DefaultConfig

imagix_config = 	DefaultConfig(
    checkpoint_interval=100,
    epochs=100,
    beta=0.1,
    latent_dim=6,
    batch_size=512,
    learning_rate=0.0005,
    loss_reduction="sum",
    data_config=DataConfig(
        data_info={
            "img": DataInfo(
                file_path=img_root,
                img_height_resize=32,
                img_width_resize=32,
                data_type="IMG",
                scaling="STANDARD",
            ),
            "anno": DataInfo(file_path=clin_file, data_type="ANNOTATION", sep="\t"),
        },
        annotation_columns=["CANCER_TYPE_ACRONYM"],
    ),
)
imagix = acx.Imagix(config=imagix_config)
imagix_result = imagix.run()
Before we make the comparison, we can quickly check the imagix reconstruction capability with imagix.visualizer.show_image_recon_grid() showing original and reconstructed images from the test-split.
fig_imagix = imagix.visualizer.show_image_recon_grid(
	result=imagix_result,
	n_samples = 10, # Number of (random) test samples to show
)
Looks good with small deviations. Let's compare with the XModalix:
param = "CANCER_TYPE" # Aggregate over a metadata parameter
fig_pure_comparison, df_comparison = xmodalix.evaluator.pure_vae_comparison(
	xmodalix_result = backup_result, # The XModalix for comparison
	pure_vae_result = imagix.result, # The pure VAE (Imagix) for comparison
	to_key = "img.img", # The translated modality key
	param = param # The metadata parameter to aggregate over. If None, all test samples are shown individually
)
A visualization is created:
fig_pure_comparison.get_figure()
6) Apply Custom Parameters
Due to the more complex training, we have more config parameters to customize. Here we go over the different loss terms and pretraining.
    gamma: float = Field(
        default=10.0,
        ge=0,
        description="Gamma weighting factor for Adversial Loss Term i.e. for XModal Classfier training",
    )
    delta_pair: float = Field(
        default=5.0,
        ge=0,
        description="Delta weighting factor for paired loss term in XModale Training",
    )
    delta_class: float = Field(
        default=5.0,
        ge=0,
        description="Delta weighting factor for class loss term in XModale Training",
    )
The correct parametrization of these terms depends heavily on your data. We provide sensible default values in our XModalixConfig class, which are a good starting point. You can investigate the loss plots to see how much each loss contributes. For example, if your goal is to strongly preserve class information in the latent embedding, you would set delta_class higher. If you care more about generalization, you might set gamma higher.
Another important factor is pretraining. Before training a modality within the full XModalix architecture, we can pretrain that modality in its subnetwork without the XModalix constraints (adversarial, paired, class loss). This can be controlled via the pretrain_epochs parameter, which can be set either globally for all data modalities or individually per modality. Both options are shown below.
In Addition, there is a way to use another architecture for the image autoencoder. We currently offer two architectures:ImageVAEArchitecture and ImageVAEFastArchitecture.
The fast architecture does not has BatchNorm and inplace activation functions, which can speed up the training process. The ImageVAEArchitecture is the default architecture and based on Yang & Uhler.
Since we need different architecture for different data type i.e. Numeric, Image, we need to pass a model_map to the XModalix Pipeline as shown below.
import autoencodix as acx
from autoencodix.configs.xmodalix_config import XModalixConfig
from autoencodix.configs.default_config import DataConfig, DataInfo, DataCase
from autoencodix.base._base_dataset  import DataSetTypes

from autoencodix.modeling._imgfast_architecture import ImageVAEFastArchitecture
from autoencodix.modeling._imagevae_architecture import ImageVAEArchitecture
from autoencodix.modeling._varix_architecture import VarixArchitecture

xmodalix_config = XModalixConfig(
    class_param="CANCER_TYPE_ACRONYM",
    gamma=2,
    delta_class=10.0,  # increase this if you care about class info in embedding
    delta_pair=3.0,
    requires_paired=False,
    pretrain_epochs=2,  # can be overridden on data level, see below
    data_case=DataCase.IMG_TO_BULK,
    data_config=DataConfig(
        data_info={
            "img": DataInfo(
                file_path="YOUR_PATH",
                data_type="IMG",
                translate_direction="to",
                pretrain_epochs=2,  # this overrides global pretraining_epochs
            ),
            "rna": DataInfo(
                file_path="YOUR_PATH",
                data_type="NUMERIC",
                translate_direction="from",
            ),
            "anno": DataInfo(file_path="YOUR_PATH", data_type="ANNOTATION", sep="\t"),
        },
    ),
)
model_map = {DataSetTypes.NUM: VarixArchitecture, DataSetTypes.IMG: ImageVAEFastArchitecture}
xmodalix = acx.XModalix(config=xmodalix_config, model_map=model_map)
7) Save, Load and Re-use XModalix
This works for XModalix as for any other models, by using the save and load methods.
import os
import glob

outpath = os.path.join("xmodalix")
xmodalix.save(file_path=outpath, save_all=False)

folder = os.path.dirname(outpath)
pkl_files = glob.glob(os.path.join(folder, "*.pkl"))
model_files = glob.glob(os.path.join(folder, "*.pth"))

print("PKL files:", pkl_files)
print("Model files:", model_files)

# the load functionality automatically will build the pipeline object out of the three saved files
xmodalix_loaded = acx.XModalix.load(outpath)
# now you can use the model to predict with a different pair again:
testdata = backup_result.datasets
r = xmodalix_loaded.predict(data=testdata)